Loading the site. Press Escape to skip the intro.

Software & Applied AI

Manankumar Thakkar

Software Engineer · AI Engineer · Applied AI

I build backend systems at Walmart Global Tech and applied-AI tools you can inspect.

Currently building atWalmart Global Tech
Meet Manan

About

Production systems. Measured AI.

Here’s my story.

I’m a Software Engineer III at Walmart Global Tech, building backend services for in-store advertising. I work on API performance, multi-tenant data design and AI tooling. Outside work, I build public AI projects and share the code, results and open questions.

Proof · Distributed systems

Fixed an N+1 API bottleneck with concurrent caching at Walmart: 60% lower latency and 10,000+ fewer DB calls/day.

Depth reflects my experience in each area.

Experience · 03

From interfaces to infrastructure.

A few career moves…

  1. Walmart Global Tech

    Software Engineer III

    Feb 2025 - Present

    • Fixed an N+1 query bottleneck with concurrent caching, reducing API latency by 60% and database calls by 10,000+ a day.
    • Built an AI operations assistant with Python, Flask and LangChain, including session memory and response caching.
    • Prevented data key collisions during international expansion by introducing a country-scoped key.
  2. Walmart Global Tech

    Software Engineer

    Jul 2024 - Jan 2025

    • Built backend services for department hours across 4,000+ stores.
    • Built location-to-screen-group mapping to support new retail formats.
  3. George Mason University

    AI Research Assistant

    Jul 2023 - Jul 2024

    • Automated manual research workflows with ChatGPT-powered tooling.
    • Made research environments reproducible by provisioning and managing infrastructure as code with Terraform.
  4. Nokia

    Test Automation Engineer (co-op)

    Sep 2022 - Jun 2023

    • Built Python automation suites for high-throughput systems, reducing manual testing effort 50%.
    • Integrated automated tests into Jenkins CI/CD pipelines, reducing defect density 20%.
  5. Let It Wag

    Full Stack Developer

    Jun 2019 - May 2020

    • Built Node.js services and REST APIs for real-time data, serving 13K+ users and improving backend efficiency 20%.
    • Delivered a responsive React interface supporting 100+ user journeys.

M.S. Computer Science · George Mason University · 2023

Projects · 04

Public code, lessons learned.

Some things I've built…

Applied AI product

Archwoven
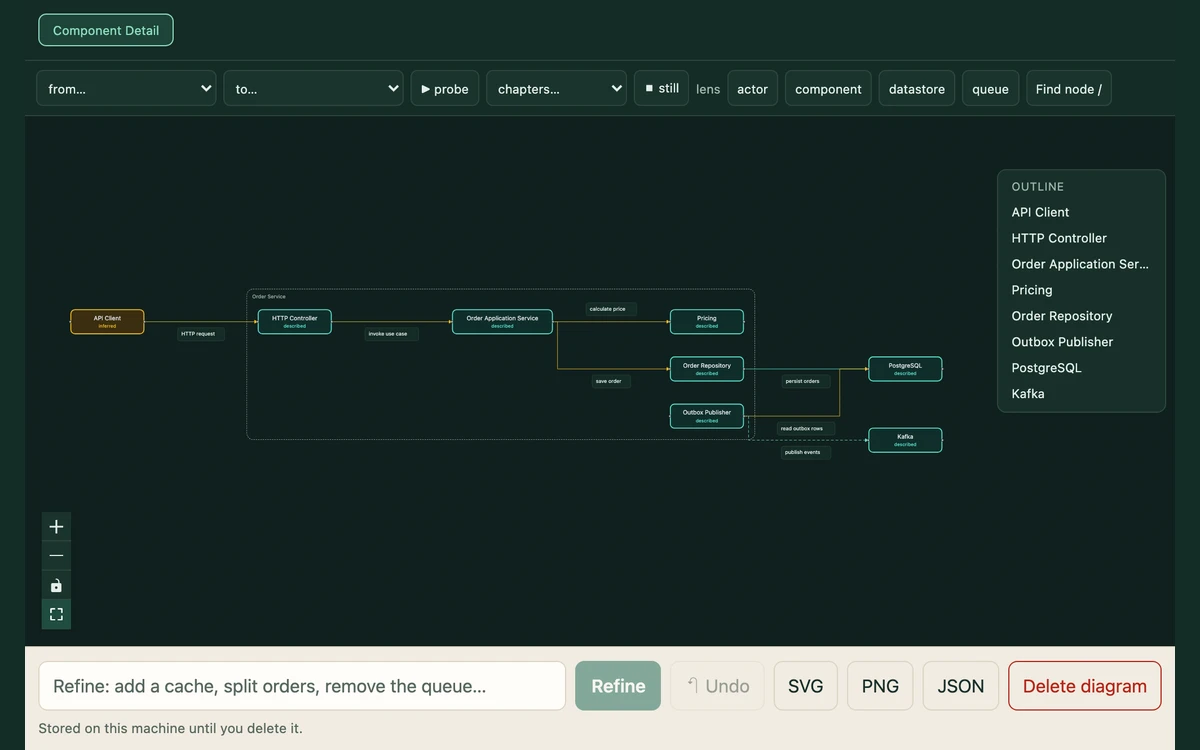
Archwoven component-detail viewer showing an order service, its controller, repository, PostgreSQL and Kafka, with refinement and export controls.
Actual viewer · recorded provider output · 17 Oct 2026
Problem
AI diagrams need an editable model and inspectable source evidence.
I built
Editable diagrams, source-backed imports, and AI token accounting with spending limits.
Outcome
4 views · SVG, PNG & JSON exports
  1. Validate model
  2. Inspect evidence
  3. Track AI usage

Hosted AI or local inference. Costs are estimates; source coverage stays explicit.

  • Next.js / React / TypeScript
  • Zod · React Flow / ELK
  • tree-sitter
  • Anthropic / Ollama
  • Redis / SQLite

Public infrastructure

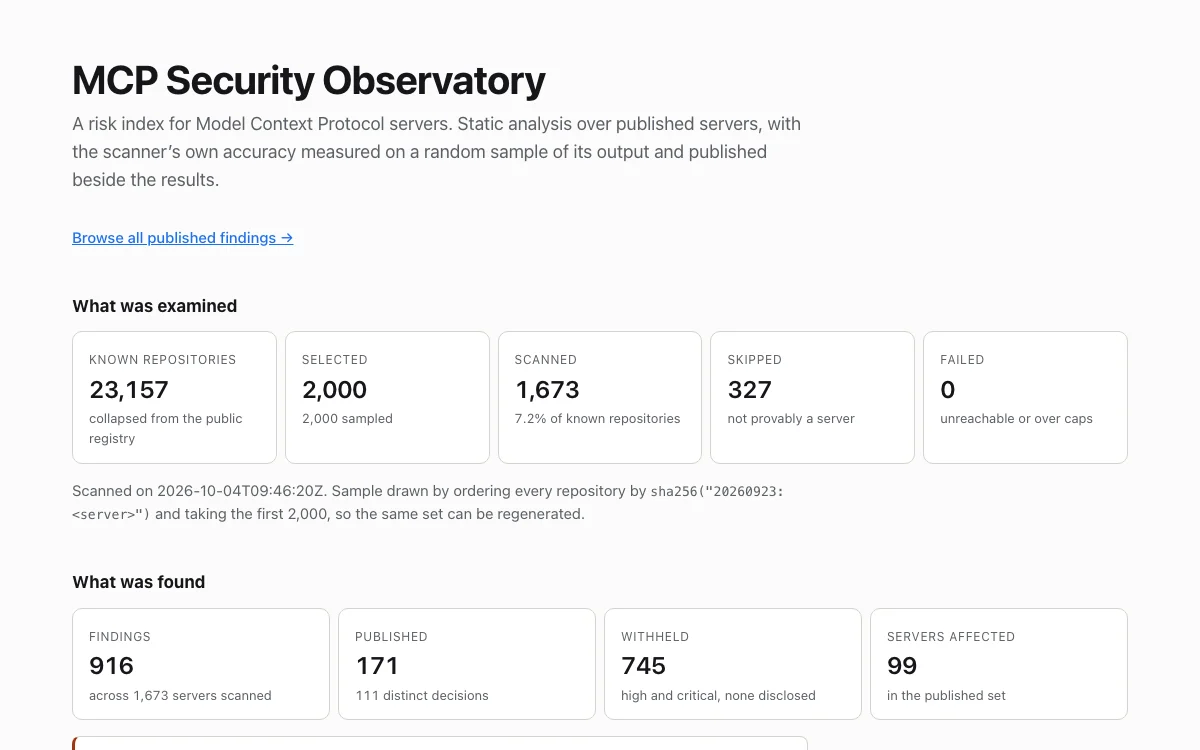
MCP Observatory

MCP Security Observatory live site, showing its scan and disclosure summaries.
Live site · 5 Oct 2026
Problem
MCP plugins can access files and shell. Review should not require running them.
I built
Static analysis, reproducible sampling, gated disclosure and a nightly public index. Sole author.
Outcome
1,673 scanned · 171 findings published
  1. Sample
  2. Inspect source
  3. Gate publication

2026-10-04 snapshot. Accuracy is unmeasured; findings are not confirmed vulnerabilities.

  • Python 3.11+
  • tree-sitter
  • SARIF / JSONL
  • pytest · ruff · mypy
  • GitHub Actions / Pages

Applied AI experiment

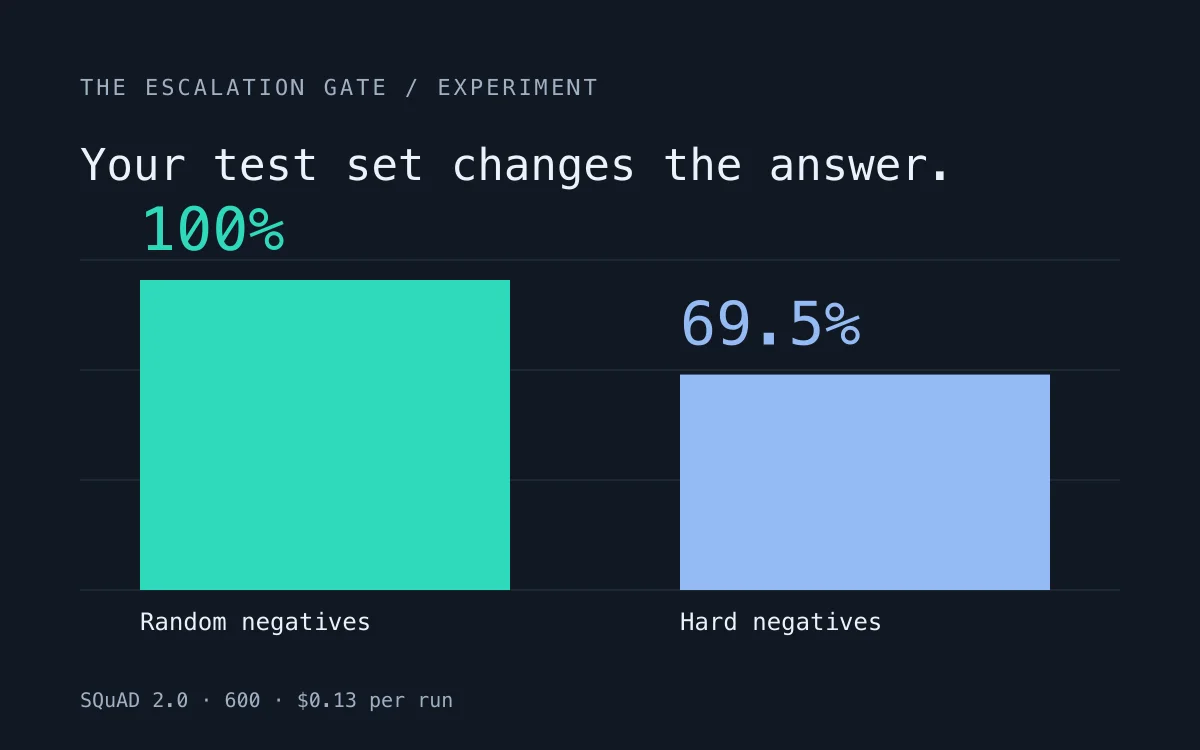
The Escalation Gate

The same answerability gate scored 100% with random negatives and 69.5% with hard negatives.
Same model · same prompt
Problem
RAG pipelines pay for generation even when retrieval cannot answer the question.
I built
A three-group answerability evaluation, calibration analysis and billing audit. Sole author.
Outcome
100% → 69.5% with hard negatives
  1. Question + passage
  2. Typed decision
  3. Route the judgment

600 SQuAD-derived decisions · ~$0.13. Floor per author audit; enterprise transfer untested.

  • Python 3.11+
  • Jev (TypeSafe AI)
  • SQuAD 2.0
  • LLM evaluation / calibration

Contact · 05

Let's build
what's next.

Software Engineer · AI Engineer · Applied AI

Let's connect

Start a conversation

Manankumar ThakkarUnited States